


Hi everyone,
In this edition of The Weekly Kaitchup:
Which NVFP4 Version of Qwen3.6 27B Should You Use?
DSpark: DeepSeek’s New Speculative Decoding Method
I’m at the ACL 2026 and stopped by the Qwen corner to ask the important question:
Should we expect Qwen3.7 27B soon?
Answer:
We haven’t made a final decision yet, but we’re committed to open-sourcing more models and have some exciting releases coming soon.
Not very informative… It sounds like a well-prepared answer. And they told me they already got this question a lot during just a single morning at the conference.
Which NVFP4 Version of Qwen3.6 27B Should You Use?
NVIDIA released an NVFP4 version of Qwen3.6 27B. It is a good occasion to revisit the other NVFP4 variants that have been released and to put NVIDIA’s checkpoint into context.
When I published my evaluations and analysis of quantized Qwen3.6 27B, only a few NVFP4 versions were available. There were so few that I had to make one myself with AutoRound.

kaitchup/Qwen3.6-27B-autoround-nvfp4-linearattn-mtp-BF16
This is my version made with AutoRound. It uses NVFP4 while keeping the linear-attention and MTP layers in 16-bit. The model size is 28.6 GB.
Peutlefaire/Qwen3.6-27B-NVFP4
This version goes further and quantizes more linear_attn layers too. The model size is 20.6 GB, with a 19.7 GB main model file and an 849 MB MTP file. Compared with my AutoRound MTP BF16 version, that is roughly 8.0 GB smaller.
In my analysis, I showed that quantizing the attention path to NVFP4 significantly degraded the model. It did not break the model, but it made it more prone to endless thinking, and accuracy went down on nearly all benchmarks. Check the full analysis for details.
unsloth/Qwen3.6-27B-NVFP4
Unsloth also released an NVFP4 checkpoint. Its config applies NVFP4 quantization to most Linear layers, while leaving some of the linear-attention projections (linear_attn.out_proj) in BF16. You can see it as a version between mine and a full NVFP4 quantization. The model size is 26.4 GB.
nvidia/Qwen3.6-27B-NVFP4
The NVIDIA version is interesting because it is mixed precision: attention and linear-attention projections are FP8 W8A8, while the MLP layers and LM head are marked as W4A16_NVFP4. The checkpoint is 21.9 GB, which makes it 6.7 GB smaller than my 28.6 GB AutoRound MTP BF16 version and 4.5 GB smaller than Unsloth’s 26.4 GB version.
This also means that the NVFP4 parts of NVIDIA’s model do not use NVFP4 activations. They are W4A16: 4-bit NVFP4 weights, but 16-bit activations. The attention path, meanwhile, is FP8 rather than NVFP4. With Blackwell GPUs, this likely leaves speed on the table compared with W4A4 NVFP4. In my experience, NVFP4 activations can be almost harmless with good calibration.
Another important detail: NVIDIA’s config.json includes an FP8 KV-cache scheme. That matters a lot for speed and memory use, especially on devices where memory bandwidth is the bottleneck. I already saw some third-party speed comparisons on X comparing this checkpoint against other NVFP4 models without matching the KV-cache format, which is not an apples-to-apples comparison. At minimum, KV-cache dtype should be controlled explicitly across all models; vLLM, for example, can be run with an explicit FP8 KV cache.
NVIDIA also reports its own evaluation numbers against an FP8 baseline. In their table, the NVFP4 checkpoint is very close to the FP8 checkpoint across MMLU-Pro, GPQA Diamond, HLE, τ²-Bench, MMMU Pro, SciCode, AIME 2025, AA-LCR, and IFBench. This is useful, but it is still not a community-wide comparison against the other NVFP4 checkpoints under identical settings.
It is also worth mentioning the PrismaQuant family.
rdtand/Qwen3.6-27B-PrismaQuant-5.5bit-vllm
This version uses a sensitivity-driven per-Linear allocation. PrismaQuant chooses between NVFP4, MXFP8, and BF16 under a 5.5-bit-per-parameter target. According to the model card, bulk dense MLP layers are usually NVFP4 W4/A4, higher-sensitivity dense linears can be MXFP8 W8/A8, and the most sensitive tensors, norms, biases, embeddings, and LM head stay BF16.
The model size is 22.7 GB, which slighly larger to the one released by NVIDIA, probably due to the LM head staying at higher precision.
There are newer PrismaQuant-family variants too. PrismaAURA 5.5-bit uses an AURA/KL-Fisher allocation over NVFP4, FP8, and BF16, while PrismaSCOUT 5.31-bit is described as a Blackwell-oriented successor to the earlier 5.5-bit PrismaQuant artifact. PrismaSCOUT uses NVFP4 plus selected BF16, includes MTP tensors, and its repository is 20.2 GB.
How to Choose?
We do not yet have a good comparison. Quantization is cheap; evaluation is expensive.
What we need is a benchmark suite run on all these checkpoints with exactly the same settings: same inference engine, same chat template, same thinking mode, same KV-cache dtype, same context length, same sampling settings, same MTP/speculative-decoding settings, and same hardware.
Until then, I would assume the following:
There is no strong reason to keep all activations in 16-bit on Blackwell if NVFP4 activation quantization is well calibrated.
Keeping the attention path out of NVFP4 is safer.
Unsloth’s version and my AutoRound version are safer choices if your priority is a more conservative quantization strategy.
PrismaSCOUT and the other PrismaQuant-family models are worth testing, but I would not rank them without independent, apples-to-apples accuracy numbers. This could be the best version. We simply don’t know.
So, for now, I would use either Unsloth’s version or my AutoRound MTP BF16 version if accuracy safety is the main concern. They are also better documented and easier to reason about than many one-off community checkpoints. If memory footprint matters more, NVIDIA’s version and PrismaSCOUT are especially interesting.
DSpark: DeepSeek’s New Speculative Decoding Method
DSpark is a speculative decoding method for making LLMs generate faster without changing the final model that verifies the text.
Instead of asking the full model to produce one token at a time, DSpark, like any other speculative decoding method, lets a smaller draft module propose several future tokens, then asks the full model to verify those tokens in a batch. When the draft is right, the server accepts multiple tokens from one target-model pass. When the draft is wrong, the server keeps the longest valid prefix and continues from there.
The target model we want to accelerate remains the source of truth, while the drafter tries to guess what the target model is likely to accept next.
What DSpark Changes
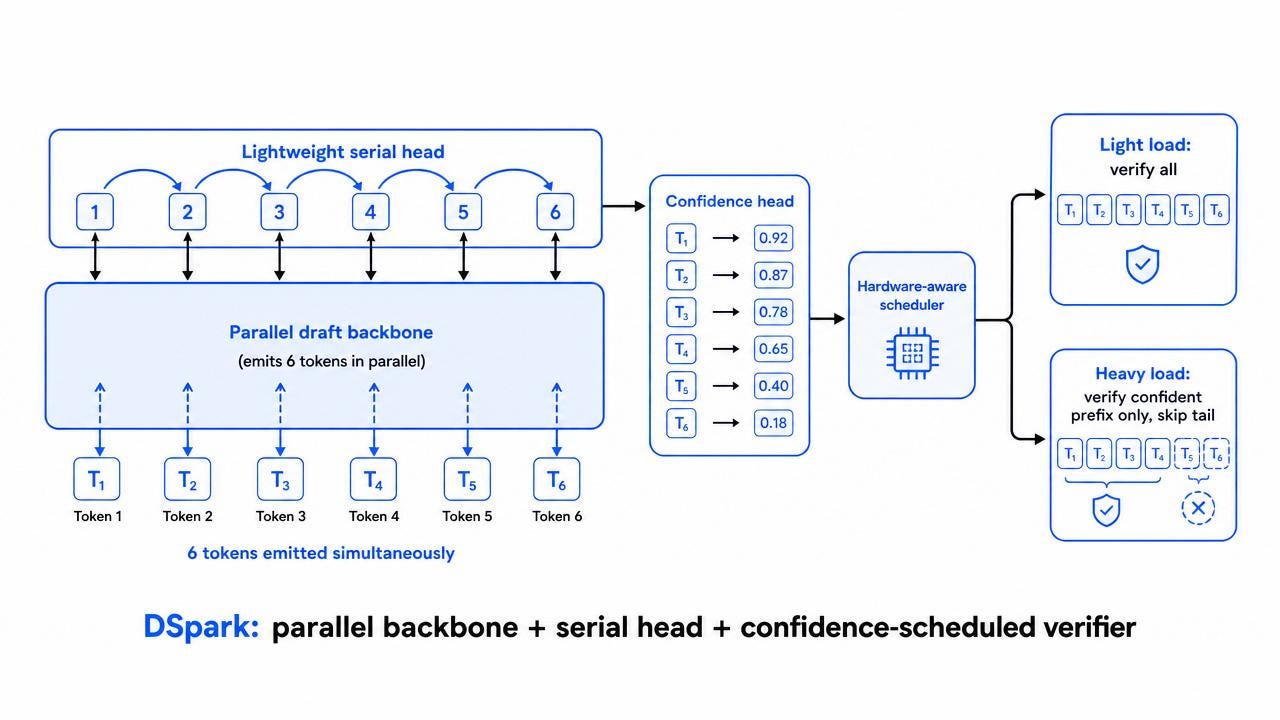
The weakness of many speculative decoders is suffix decay. Drafting the first token is easy but drafting the fifth, sixth, or seventh token is much harder because every position depends on earlier guesses. Fully parallel drafters are fast, but later draft positions often become noisy. Autoregressive drafters are more faithful, but they give back too much of the latency advantage because they draft sequentially.
DSpark tries to sit between those two extremes. It keeps a DFlash-style parallel draft backbone, then adds a lightweight Markov logit-bias head. Note: I explained how DFlash works here:

That head lets each draft position condition on previously sampled tokens inside the draft block, which improves the later positions without turning the whole drafter into a slow autoregressive model.
The other important piece is confidence. DSpark adds a confidence head that predicts the acceptance probability of each draft position. That gives the serving system a practical scheduling signal. When the drafter is confident, the runtime can verify more proposed tokens. When confidence drops, or when the server is under load, it can avoid wasting verification work on tail tokens that are likely to be rejected. In other words, DSpark is not just a better drafter; it is a more serving-aware drafter.
How it works in the decoding loop
At each generation step, DSpark first prepares a block of draft tokens. The target model then scores that block in one verification pass. The runtime accepts the longest prefix that agrees with the target model’s sampling path and discards the rest. If several drafted tokens survive, the user sees several tokens produced for roughly one target-model step. If only the first token survives, the system behaves closer to normal decoding for that step.
The Markov head just helps the drafter keep later draft positions coherent. The confidence head helps the runtime decide how much speculation is worth attempting. Together, they attack the two practical bottlenecks of speculative decoding: low acceptance at later positions and wasted verification work under real serving load.
Speed results
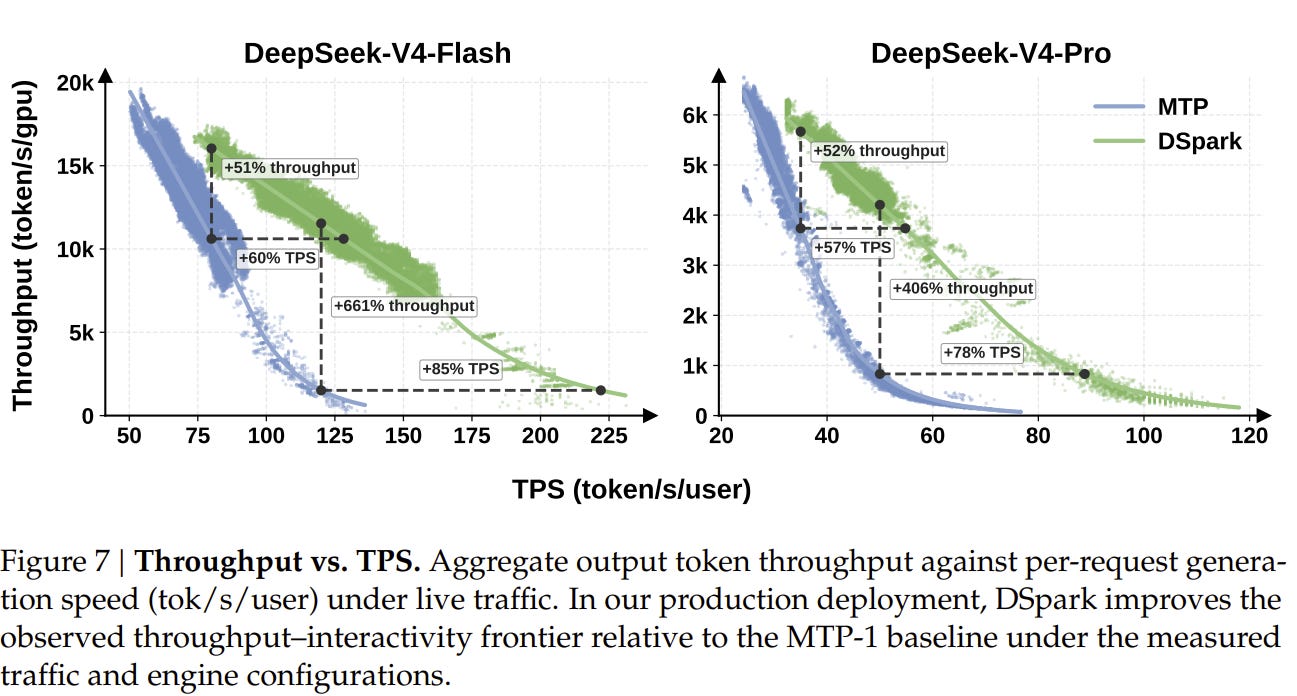
DSpark improves per-user generation speed by about 60–85% over the previous MTP-1 baseline on DeepSeek-V4-Flash, and by about 57–78% on DeepSeek-V4-Pro at matched throughput. Offline accepted-length results also reportedly improve over Eagle3 and DFlash. As usual with speculative decoding, the exact gain depends on the prompt mix, sampling settings, hardware, batch pressure, and how often the drafter’s later tokens are accepted. Once widely available for other open-weight models, like Qwen3.6 and the larger Gemma 4, it will be interesting to see how fast is it compared with high MTP, like MTP-4 or 5 which are much faster than MTP-1 for these two models.

You can find more results in the technical report:
DSpark: Confidence-Scheduled Speculative Decoding with Semi-Autoregressive Generation
What DeepSeek released
The DeepSpec repository currently includes three draft-model algorithms: DSpark, DFlash, and Eagle3.
DeepSeek also released trained draft checkpoints for four target models: Qwen3-4B, Qwen3-8B, Qwen3-14B, and Gemma-4-12B-it. For each target, the repo lists Eagle3, DFlash, and DSpark checkpoints, so the open release covers twelve reference draft checkpoints.
DSpark checkpoints are also available for DeepSeek V4 Flash and Pro.
Running DSpark in vLLM
DSpark support is landing in vLLM through the speculative decoding path. The relevant vLLM PR for DSpark speculators-format checkpoint support was merged on July 2, 2026, so use a nightly build or a release that includes that change.
uv pip install -U vllm --extra-index-url https://wheels.vllm.ai/nightly

vllm serve deepseek-ai/DeepSeek-V4-Flash-DSpark \
  --tensor-parallel-size 8 \
  --speculative-config '{"method":"dspark","num_speculative_tokens":5,"draft_sample_method":"probabilistic"}'
Training your own DSpark speculator
You can train a DSpark speculator on your own data for Qwen3 and GLM 5.2 (only these architectures are support for now) using the speculators project. This is very similar to training a DFlash a speculator.
That’s all for this week.
If you like reading The Kaitchup, consider sharing it with friends and coworkers (there is a 20% discount for group subscriptions):
Have a nice weekend!
While saving VRAM is obviously good, I have had endless issues with NVFP4 quants for agentic coding. They work well for smaller contexts and a limited number of turns, but often break down at some point with looping, miss-spellings, confusion and other weirdness compared to the original `Qwen/Qwen3.6-27B-FP8` on vLLM. For example the speed of `rdtand/Qwen3.6-27B-PrismaSCOUT-Blackwell-NVFP4-BF16-vllm` was really excellent on an RTX PRO 6000, but it started to misspell specific words after a while, and this caused chaos in the produced commands and code, with the agent repeatedly correcting itself.
So my question is, am I leaving useful quality on the table by using NVFP4 or even FP8 compared to say BF16 for Qwen3.6-27B? The benchmarks show minimal differences, yet my anecdotal experiences tell me that as the number of "turns" increase in an agentic workflow, the quantization artifacts stack up.
Btw, could Mix-Quant (https://arxiv.org/html/2605.20315v1) be helpful here?
There is also Quant-Claw: https://arxiv.org/html/2604.22577v1
Are there practical routes to use them in OpenCode or something similar?
I worked with claude to build a basic quantization tool based on a lot of your writing around the qwen model and autoround. Lots of fun and learning, thank you so much for these articles!!